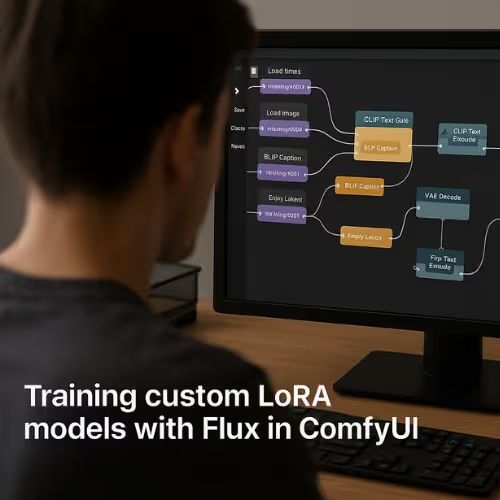


How to Use LoRA with ComfyUI: A Step-by-Step Guide
Training a LoRA model locally means fine-tuning a Stable Diffusion or Flux model on your own images, running entirely on your GPU — no cloud service, no subscription, no data leaving your machine.
The process takes 3–5 hours for a 20–50 image dataset on a modern GPU. You need: a compatible GPU with at least 12GB VRAM, your training images at 1024×1024 resolution, the base Flux or Stable Diffusion model files, and a local AI app to manage the workflow.
This guide walks through every step from image preparation to testing your finished LoRA.
Training a custom LoRA locally gives you something no cloud tool can offer: a model trained on your exact subject, running privately on your own hardware, with no per-generation cost and no content restrictions. Whether you want to teach an AI to replicate a specific art style, generate consistent characters, or recreate a product or face, local LoRA training is how you do it.
This guide covers the complete process for training LoRA models using Flux — currently the strongest open-source architecture for local training — running on your own GPU. No Python setup required if you use Promptus, which handles the environment automatically.
What you need before you start: hardware and software requirements
Training a LoRA model locally requires a compatible NVIDIA GPU with at least 12GB VRAM for Flux-based training. You can train with 8GB VRAM using lower-resolution datasets, but expect longer training times and some quality tradeoffs. AMD GPUs are supported via ROCm on Linux but require additional configuration.
GPU requirements
| GPU | VRAM | Est. Time | Notes |
|---|---|---|---|
| RTX 4090 / 4080 | 24GB / 16GB | ~2.5 hrs | Recommended for Flux full training |
| RTX 3090 / 3080 | 24GB / 10GB | ~4 hrs | 3080 may need batch size 1 |
| RTX 4070 / 3070 | 12GB / 8GB | ~5 hrs | Use FP8 quantized Flux model |
| RTX 4060 / 3060 | 8GB | 6+ hrs | Reduce image resolution to 768×768 |
Software setup
The simplest way to set up a local LoRA training environment is through Promptus, which installs all dependencies — CUDA, Python, the trainer nodes, and model management — in a single download.
flux1-dev.safetensors or the FP8 variant for lower VRAMclip_l.safetensors and t5xxl_fp8_e4m3fn.safetensorsae.safetensorsHow to prepare your training dataset
Dataset quality determines LoRA quality. A poorly prepared dataset — images with inconsistent lighting, mixed subjects, or wrong resolution — produces a model that generates inconsistent or blurry results. Spending time on dataset preparation is the highest-return part of the entire process.
Image selection guidelines
- Use 20–50 images of your subject. Fewer than 20 often under-trains; more than 80 can cause over-fitting where the model memorizes instead of learning.
- Use consistent image resolution. All images should be 1024×1024 pixels. Crop and resize before training — mixed resolutions confuse the trainer.
- Vary the composition, not the subject. Use different angles, lighting, backgrounds, and distances. This teaches the model to generalize, not memorize.
- Remove duplicates and near-duplicates. Two nearly identical images count as one data point but waste training cycles.
- Name your trigger word. Choose a unique word that will activate your LoRA in prompts — something unlikely to appear in standard prompts, like
mysubject01orstudioaxyz.
Writing image captions (optional but recommended)
Captioning your training images teaches the model the relationship between text descriptions and visual content. You can generate captions automatically using the BLIP or Florence captioning workflow, or write them manually. Each caption should describe the image accurately and include your trigger word.
Example: "mysubject01, a woman with dark hair wearing a red jacket, standing in a forest, natural lighting, photorealistic."
Put the trigger word first in every caption. Generic descriptions of environment, lighting, and style at the end improve the LoRA's flexibility across different prompts.
Step-by-step: how to train stable diffusion LoRA locally
The following steps use Promptus to manage the workflow environment. If you are using a manual Python setup, the trainer parameters are identical — only the interface differs.
- Open Promptus and navigate to the Workflows tab. Search for "LoRA trainer" or "Flux trainer" in the workflow library. Download the Flux LoRA training workflow.
- Install required nodes. When the workflow loads, missing nodes will be flagged automatically. Click "Install Missing Nodes" and restart when prompted.
- Set your dataset path. Find the Dataset Path field and point it to your training images folder. Use the full path, not a relative one — this prevents the most common training error.
- Configure your output name. Set a memorable name for your LoRA file (e.g.,
mystyle_v1.safetensors). - Connect the Flux model. Link your
flux1-dev.safetensorsto the model loader node. Connect the CLIP encoders and VAE to their respective nodes. Red dashed lines mean a model file is missing. - Set training steps. For a 30-image dataset, 1,500–2,000 steps is a good starting point. Beyond ~3,000 steps on small datasets, quality typically degrades from over-fitting.
- Set learning rate. Leave at the default (0.0001 or 1e-4) for your first run. Adjust only after reviewing initial results.
- Click Run. You'll see step progress, training loss values, and preview images at regular intervals.
Training loss should decrease steadily over the first 30–40% of steps, then level off. A loss that never levels off means under-training — increase steps. A loss that drops fast then rises means over-fitting — reduce steps or expand your dataset.
Preview images should begin resembling your subject around step 800–1,000 for a 30-image dataset. If they look random at step 1,500, check your dataset path and caption loading.
How to test your trained LoRA after training completes
When training finishes, the LoRA file (a .safetensors file, typically 50–200MB) will be saved to the output location you specified. Load it into a standard image generation workflow to test it.
- Open a basic text-to-image workflow in Promptus.
- Add a LoRA loader node and point it to your newly trained file.
- Set LoRA strength to 0.8 as a starting point. Values near 1.0 apply the LoRA more strongly; values near 0.4–0.5 blend it more subtly.
- Write a test prompt using your trigger word:
"[trigger word], [description of desired output]". Test with 3–4 different prompts. - Compare outputs with the LoRA enabled and disabled. Your subject should be clearly visible when enabled and absent when disabled.
If results are off, the most common issues are: LoRA strength too low (try 0.9–1.0), trigger word missing from the prompt, or under-training (retrain with more steps or a larger dataset).
Troubleshooting: stable diffusion LoRA not showing up or not working
LoRA not showing up in your generation results is the most frequently reported issue. It almost always has one of four causes.
LoRA file not in the correct folder
The LoRA loader looks for files in models/loras/. If your file is saved elsewhere it will not appear in the selector. Move the .safetensors file to the correct folder and refresh the file list.
Trigger word missing from the prompt
If you trained with captions containing a trigger word, that exact word must appear in your generation prompt for the LoRA to activate. Without it, the LoRA may appear to have no effect. Add your trigger word at the start of the prompt.
LoRA strength set too low
A LoRA strength below 0.5 can look identical to the base model with no LoRA applied. Try increasing to 0.8–1.0 before concluding the LoRA hasn't trained correctly.
Model compatibility mismatch
LoRAs trained on Flux must be used with Flux models. A Flux LoRA cannot be loaded into a Stable Diffusion 1.5 or SDXL workflow — the architectures are incompatible. Confirm your generation workflow uses the same base model as your training run.
.safetensors file in the models/loras/ folder?
Frequently asked questions
The bottom line: local LoRA training is worth the setup
Training a custom LoRA model locally gives you something no cloud service can provide: a model that belongs entirely to you, trained on your data, running on your hardware, with no ongoing cost and no restrictions on what you can train. The one-time investment in setup time pays off in unlimited generations from a model built for your exact use case.
The fastest way to get started is to download Promptus, which installs the complete local training environment in one step — models, nodes, and workflow all included. From there, the steps in this guide apply directly with no command line required.
Start training your first LoRA today
Download Promptus → set up your dataset folder → load the Flux LoRA training workflow → click Run.
Your first custom model can be generating images within a few hours.
Most recent wikis

AI Generation Platform
Promptus AI is the easiest way to generate realistic photos, videos, 3D and ComfyUI workflows with artificial intelligence.
Our AI photo generator produces lifelike portraits, product images, and creative concepts in seconds, making it the perfect tool for creators and brands.
