AI Generator
ZONOS3-Mini
ZONOS3-Mini (often written ZONOS3 or Zonos 3) is Zyphra's open-source text-to-speech model that clones a voice from a short recording and speaks 43 languages. Zyphra released it on 9 November 2026 with the weights under Apache 2.0, so what you make can be used commercially. It is small enough to run on your own PC, and in Promptus you can run it with one click from a CosyTemplate, locally or online. Watch the full video test, where we cloned a real voice and scored ZONOS3 against ElevenLabs in eight rounds.
ZONOS3-Mini specs
| Spec | ZONOS3-Mini |
|---|---|
| Developer | Zyphra |
| Release | 9 November 2026 |
| Parameters | About 800 million in total, about 100 million active (sparse mixture of experts) |
| Languages | 43 |
| Audio | 44.1 kHz output |
| Voices | 27 built-in voices, plus zero-shot cloning from a short clip |
| Licence | Weights Apache 2.0, inference code MIT |
| Where it runs | Windows, Mac, Linux, browser (WebGPU) and phones, per Zyphra |
How ZONOS3 works
ZONOS3-Mini is a small language model for speech. It reads your text plus a description of the voice (a cloned speaker, a built-in voice or a designed one) and predicts audio tokens, which Zyphra's own audio codec, ZAC-1, turns back into a 44.1 kHz waveform. Because it is a mixture of experts, only about 100 million of its 800 million parameters work on each step, which is why it is fast enough for laptops and phones. Zyphra reports first audio in under 150 ms on an M3 MacBook Air and under 570 ms in a browser on a Pixel 9.
Voice cloning
Give it 10 to 30 seconds of one person speaking and it copies that voice, with no training step. In the ComfyUI-ZONOS3 node there are two clone methods: voice profile turns the clip into a short fingerprint and works with every slider, and raw clip uses the whole recording.
Voice design
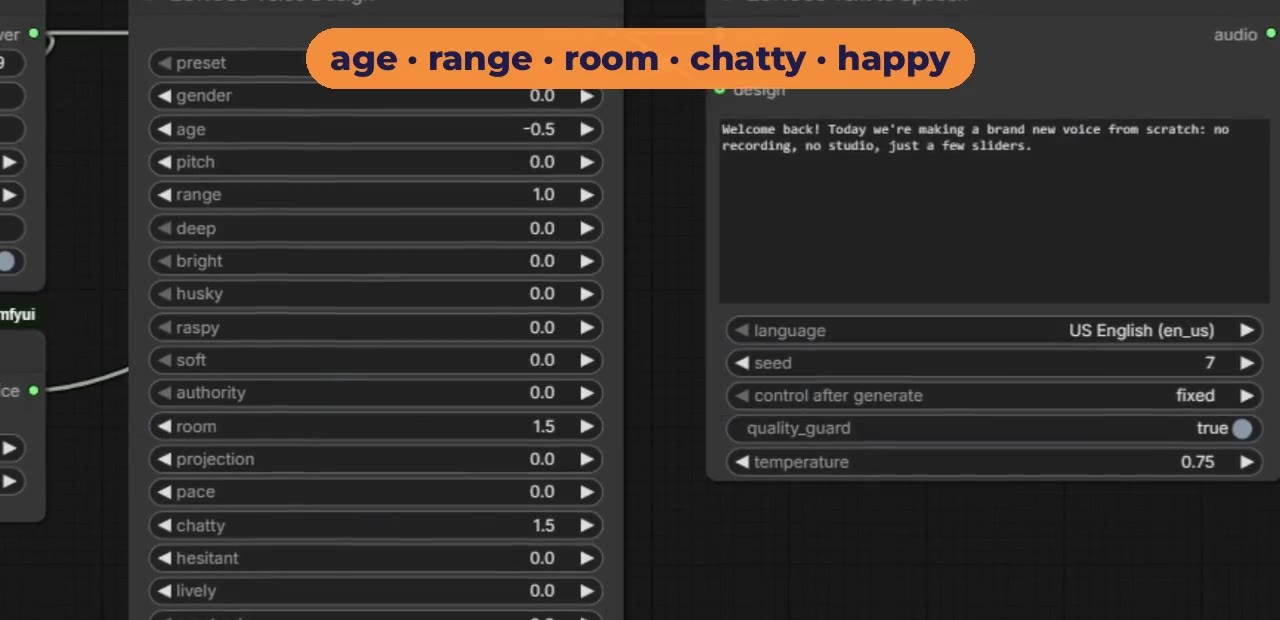
You can also make a new voice without any recording, with 25 sliders (gender, age, pitch, room, pace, happy, calm and more), 15 accents and 8 presets such as a chatty podcaster or a late-night radio host.
ZONOS3 vs ElevenLabs: our test
We cloned one real voice with ZONOS3-Mini and with an ElevenLabs v4 voice clone (default settings), ran the same eight lines through both, one take each, and scored how closely each sounded like the real speaker with two speaker-matching models. The real voice scores 91, which is the ceiling.
| Round | ZONOS3 | ElevenLabs | Point |
|---|---|---|---|
| Plain | 79 | 69 | ZONOS3 |
| Excited | 65 | 57 | ZONOS3 |
| Whisper | – | – | ElevenLabs (it really whispered) |
| Sad | 75 | 69 | ZONOS3 |
| Angry | 67 | 70 | ElevenLabs |
| Tongue twister | 81 | 73 | ZONOS3 |
| Long (about 60 s) | 88 | 77 | ZONOS3 |
| Spanish | 70 | 60 | ZONOS3 |
ZONOS3 won 6 rounds to 2 on sounding like the real voice. ElevenLabs still sounds more polished and is better at acting, especially whispering and anger. On an NVIDIA RTX 5090 Laptop GPU, ZONOS3 made six to seven seconds of speech in 0.67 to 0.83 seconds.
How to run ZONOS3 in Promptus
- Open CosyTemplates and search for ZONOS3. There are two templates: ZONOS3 - Clone Your Voice and ZONOS3 - Design a Voice.
- Choose Local to run it on your own GPU (Install Locally sets everything up once, about 2 GB), or Online to run it in the cloud.
- Upload your clip (for cloning), type your text, pick the language and press Generate. The result is saved as an MP3.
Prefer ComfyUI? The free ComfyUI-ZONOS3 node pack adds the same nodes. Our step-by-step ZONOS3 guide covers both routes, with settings and fixes.
Sources: Zyphra's ZONOS3-Mini announcement and the ZONOS3-Mini model card on Hugging Face. Speed and head-to-head results were measured by Promptus.
- YouTube and podcast voiceovers in your own voice, without recording every line.
- Dubbing: your cloned voice can speak any of the 43 languages from an English recording.
- Characters and narration for games, audiobooks and explainer videos, using the 27 built-in voices or the voice-design sliders.
- Voice agents and apps that need fast, local speech with a commercial-friendly licence.
- Private work: run it locally so your recordings never leave your computer.
Only clone your own voice, or a voice you have permission to use.
- Reference clip: 10 to 30 seconds, one speaker, no music, little background noise.
- Clone method: start with voice profile; try raw clip if you want it closer to the exact recording (it needs an extra 5.6 GB download the first time).
- Language: pick the language your text is written in. ZONOS3 does not translate; to speak Spanish, type Spanish.
- Sliders: nudge one or two at a time. Liveliness, Happy and Chatty together pushed one voice from about 97 Hz to about 394 Hz.
- Seed: if one line sounds off, change the seed and run it again.
- Quality guard: leave it on; it retakes a line if a word gets skipped.

